Customs CLVS (EAI)
 TL;DR - Governed business system, built from Gherkin requirements
Created by: › genai-logic create --project_name=demo_customs_clvs --db_url=sqlite:///samples/dbs/customs.sqlite
- Governed Business Systems: rules enforce actual CBSA CLVS eligibility regulations
- EAI (XML): incoming shipment messages mapped and matched to internal tables
- Requirements expressed in Gherkin, not prose — see
docs/requirements/customs_demo/requirements.md - A complex example of Executable Requirements — sample XML message formats, multiple requirements formats, full traceability from spec to rule to test
Browse the code: demo_customs_clvs on GitHub
Status: Reference implementation
Customs Demo
At a Glance
Process Msg Transactions
The system
- Subscribes to a broker message for shipments
- Determines which are "Customs Low Value Shipments" that require no further intervention
- Some of the classification rules are shown on the right panel
- Forwards low value shipments to the Tax System
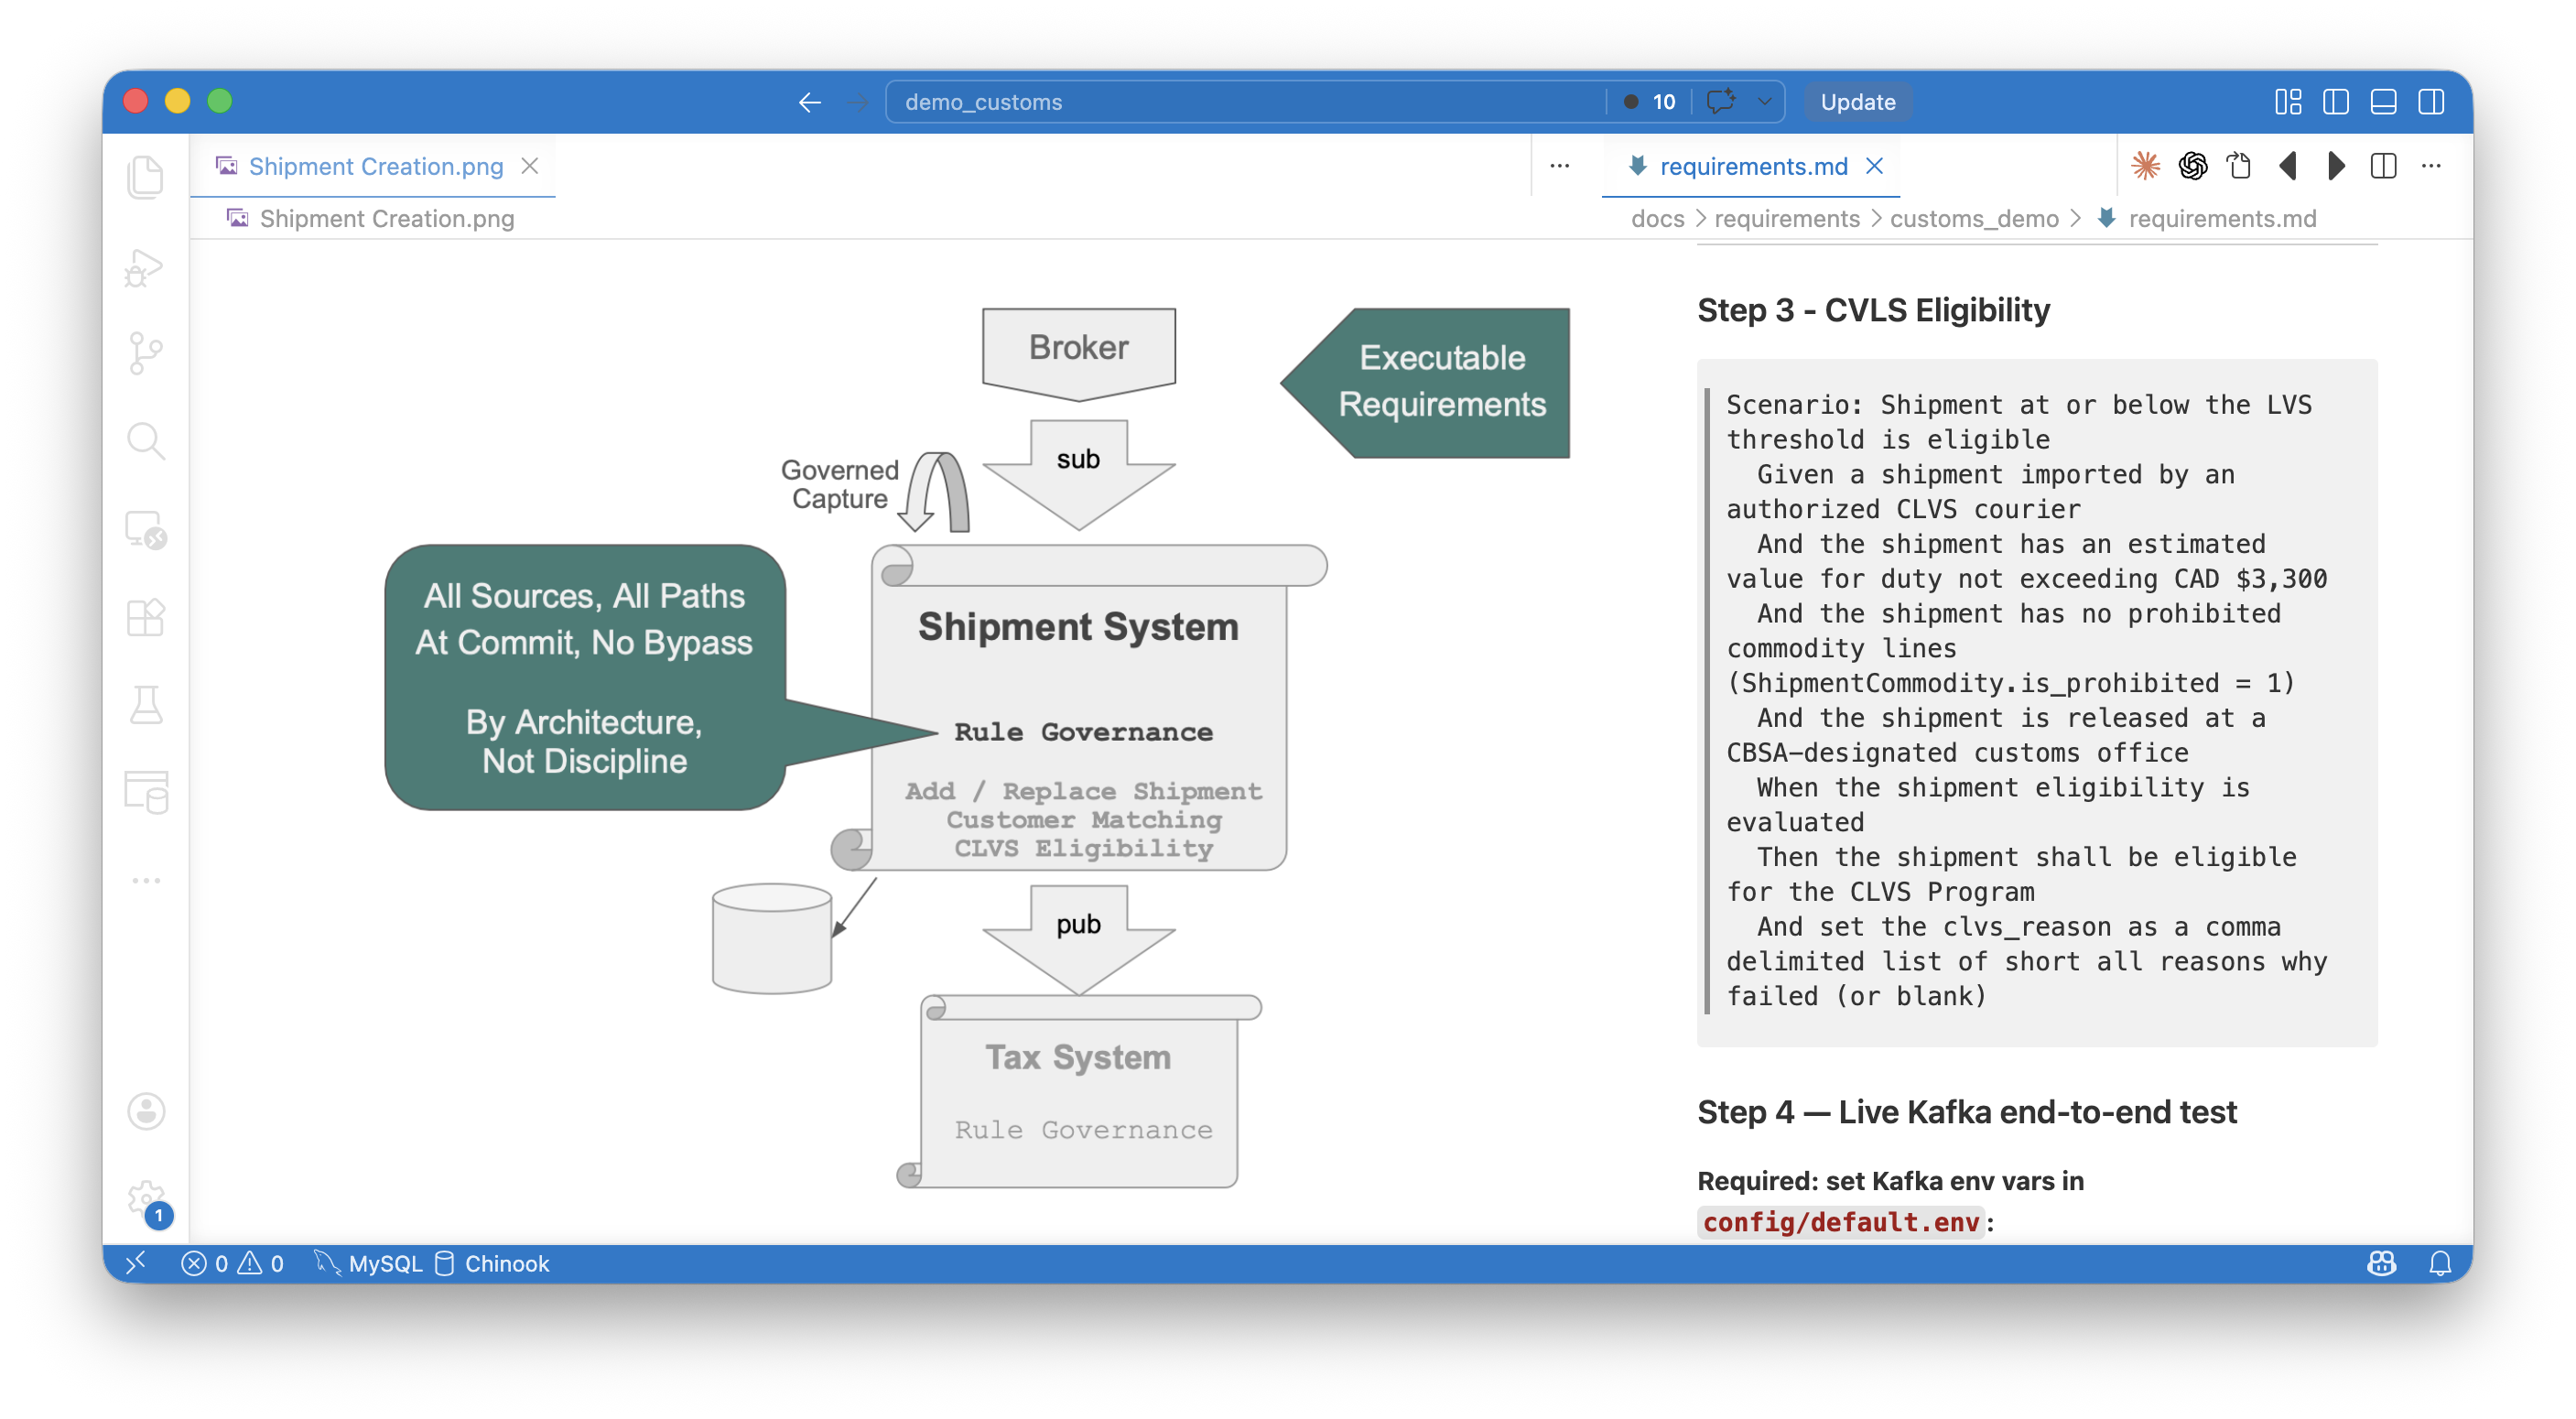
Created from Requirements
The system is created from requirements, as follows:
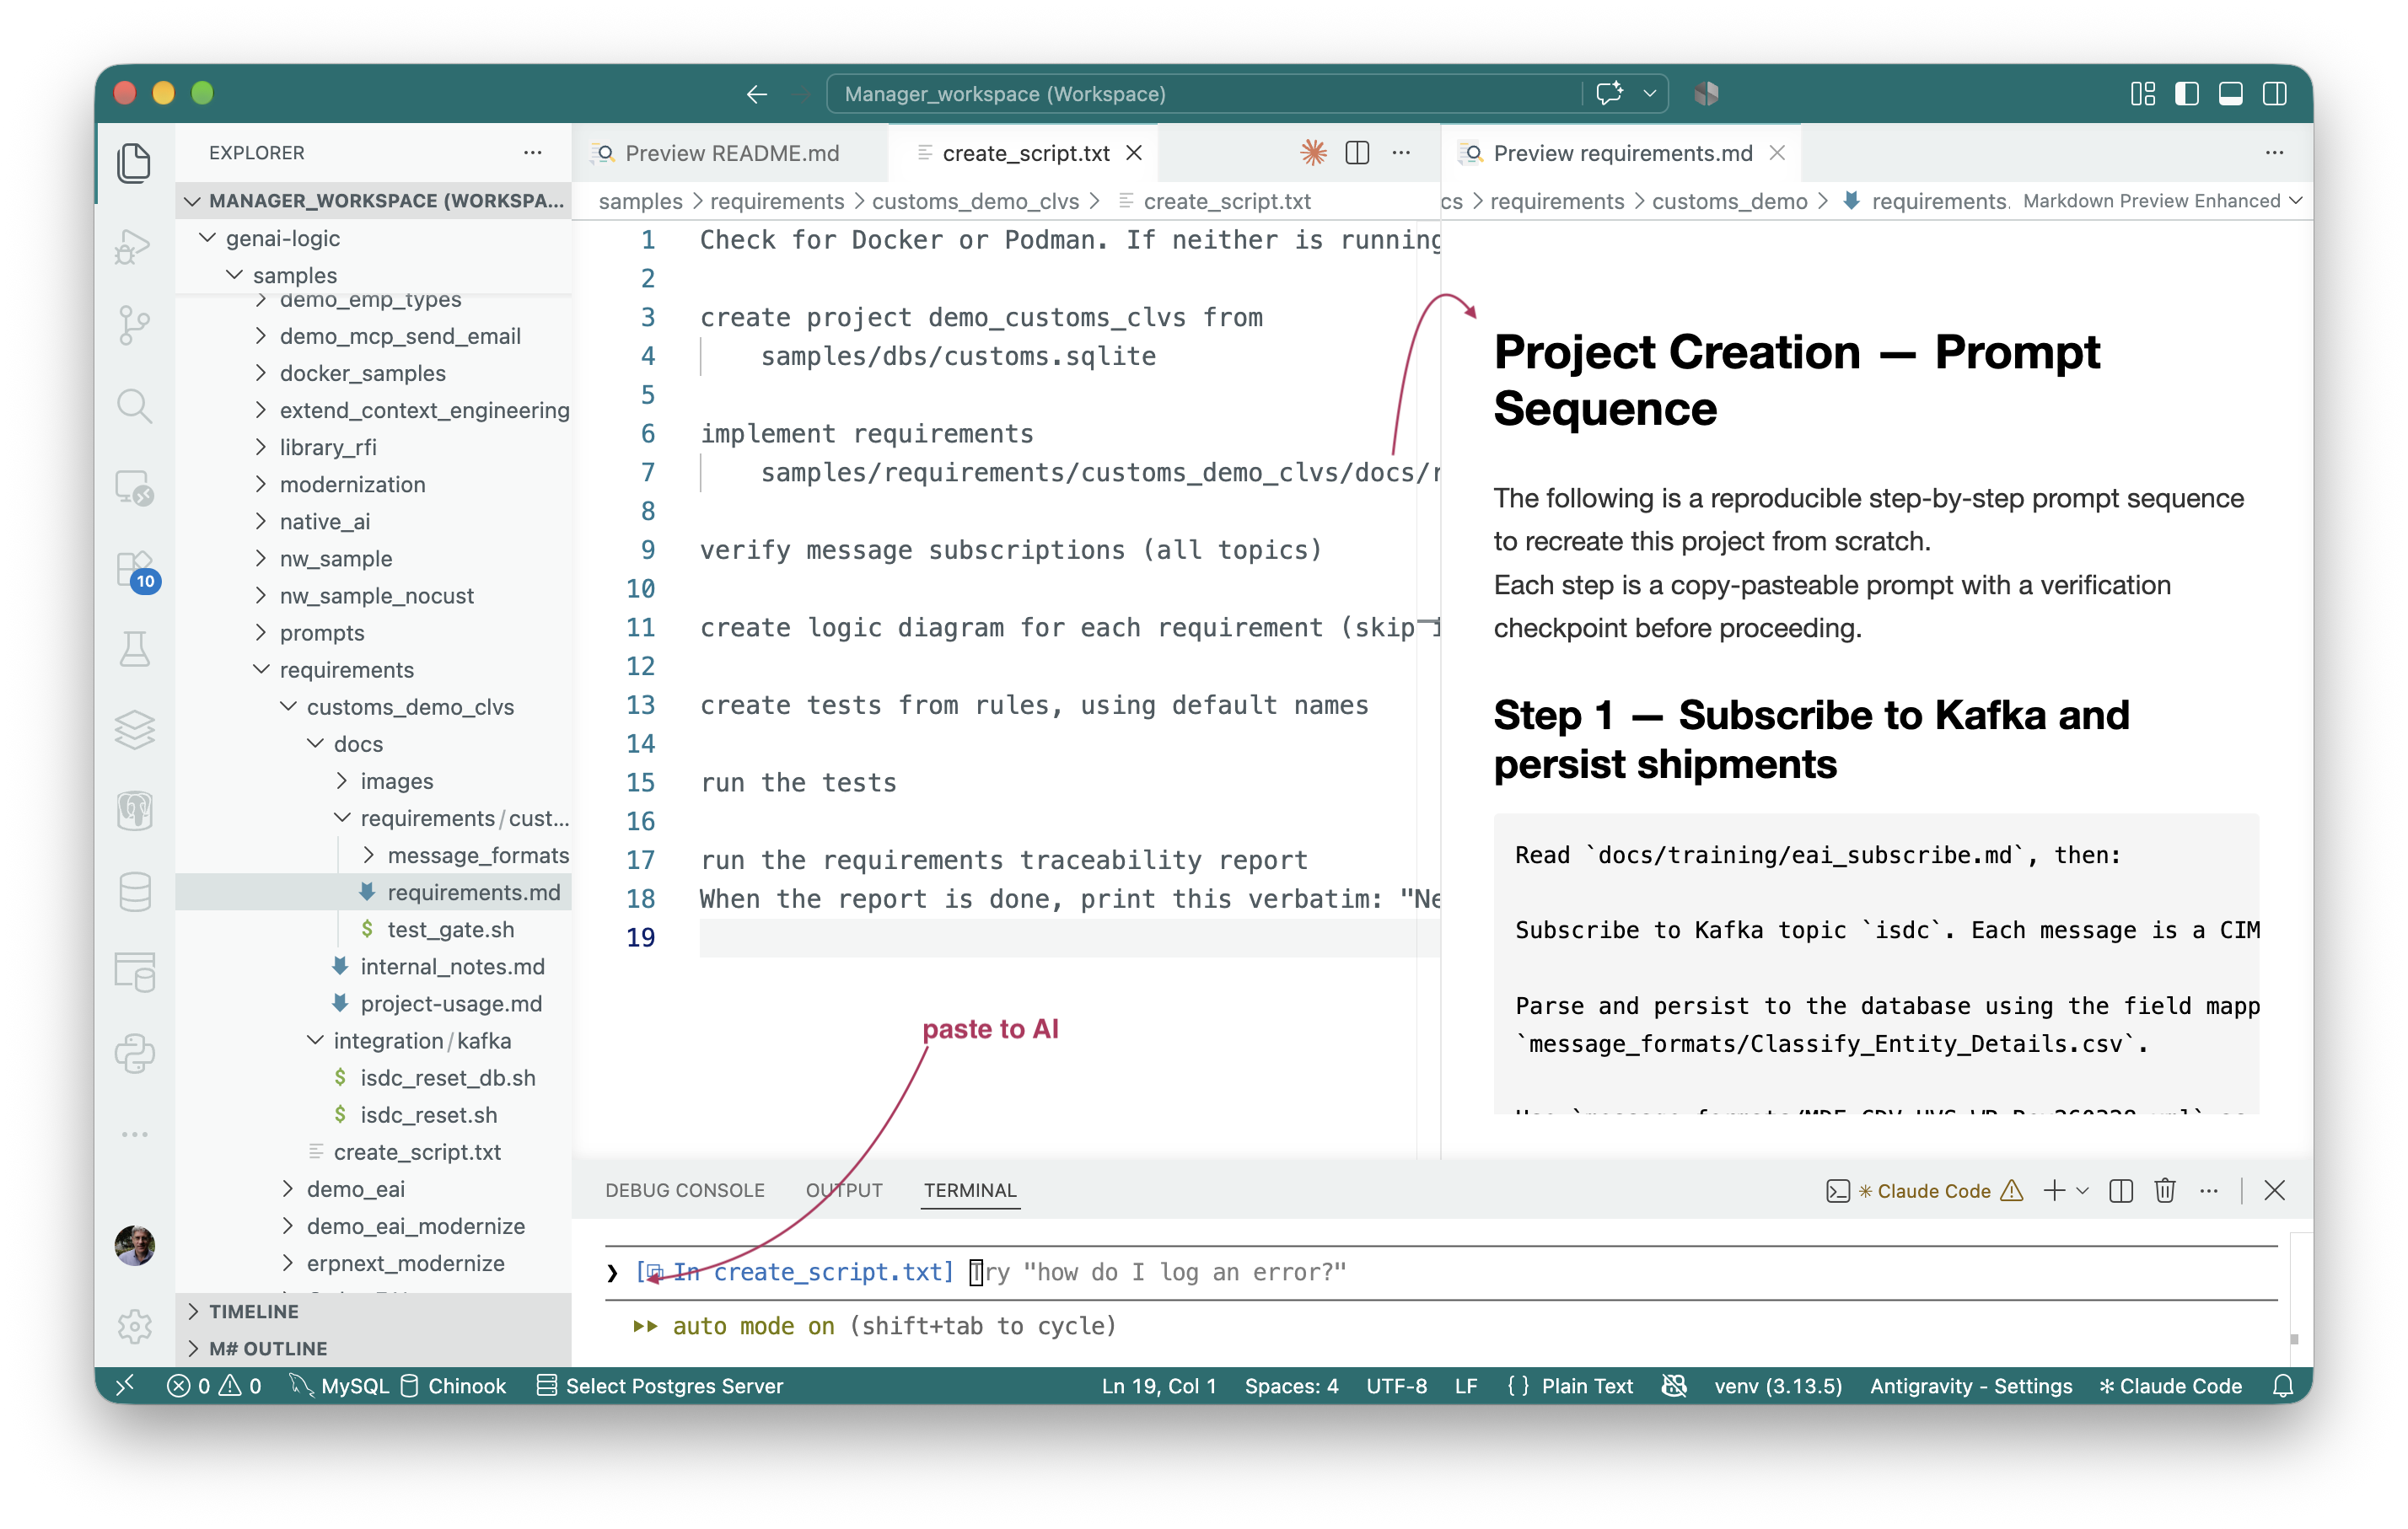
Executable Requirements - Governance By Architecture, At Scale
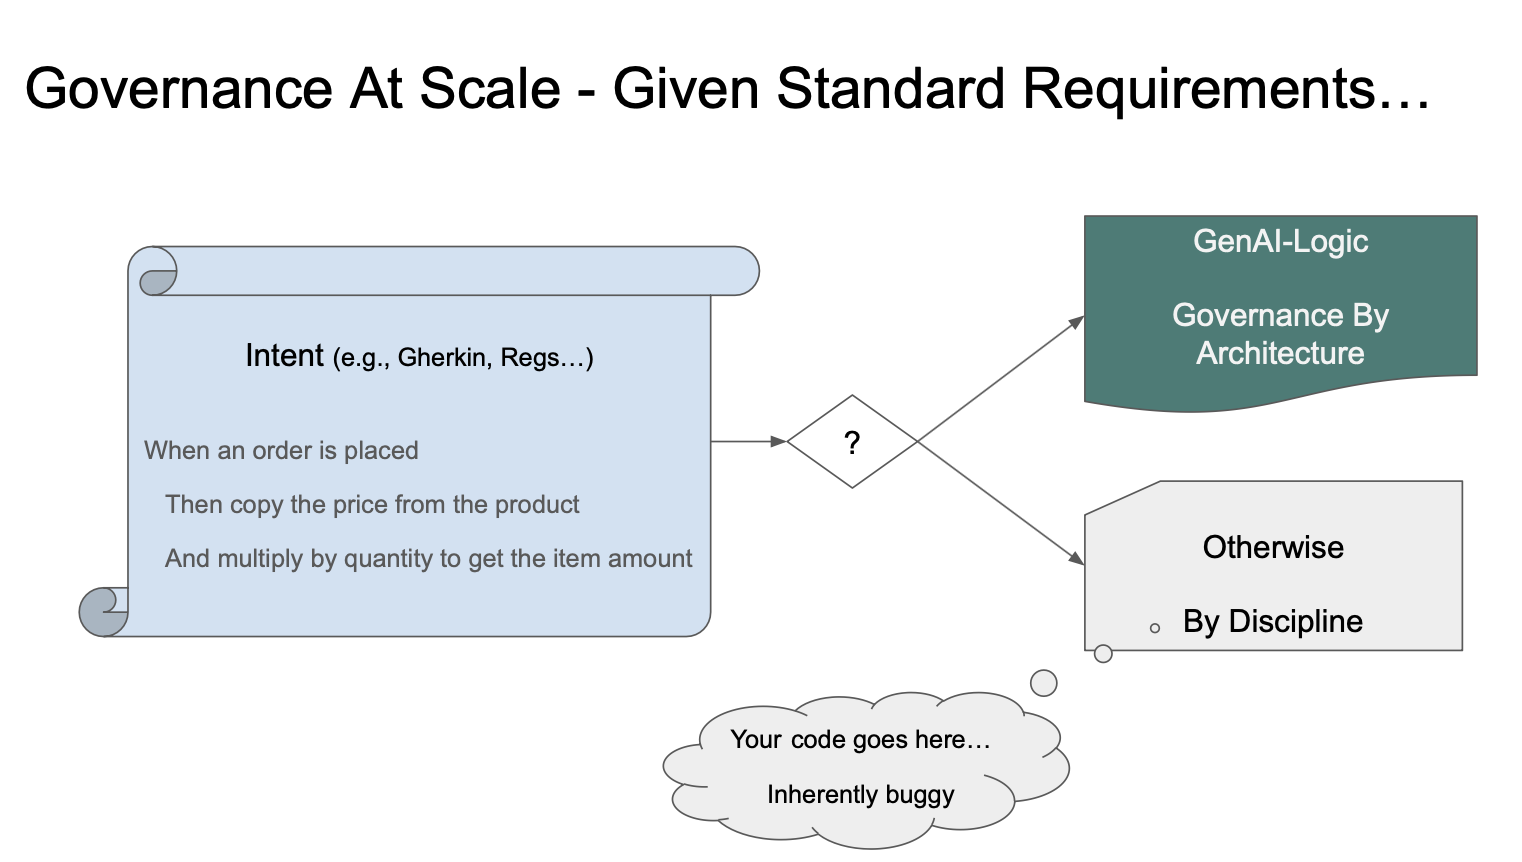
The Underlying Logic Architecture
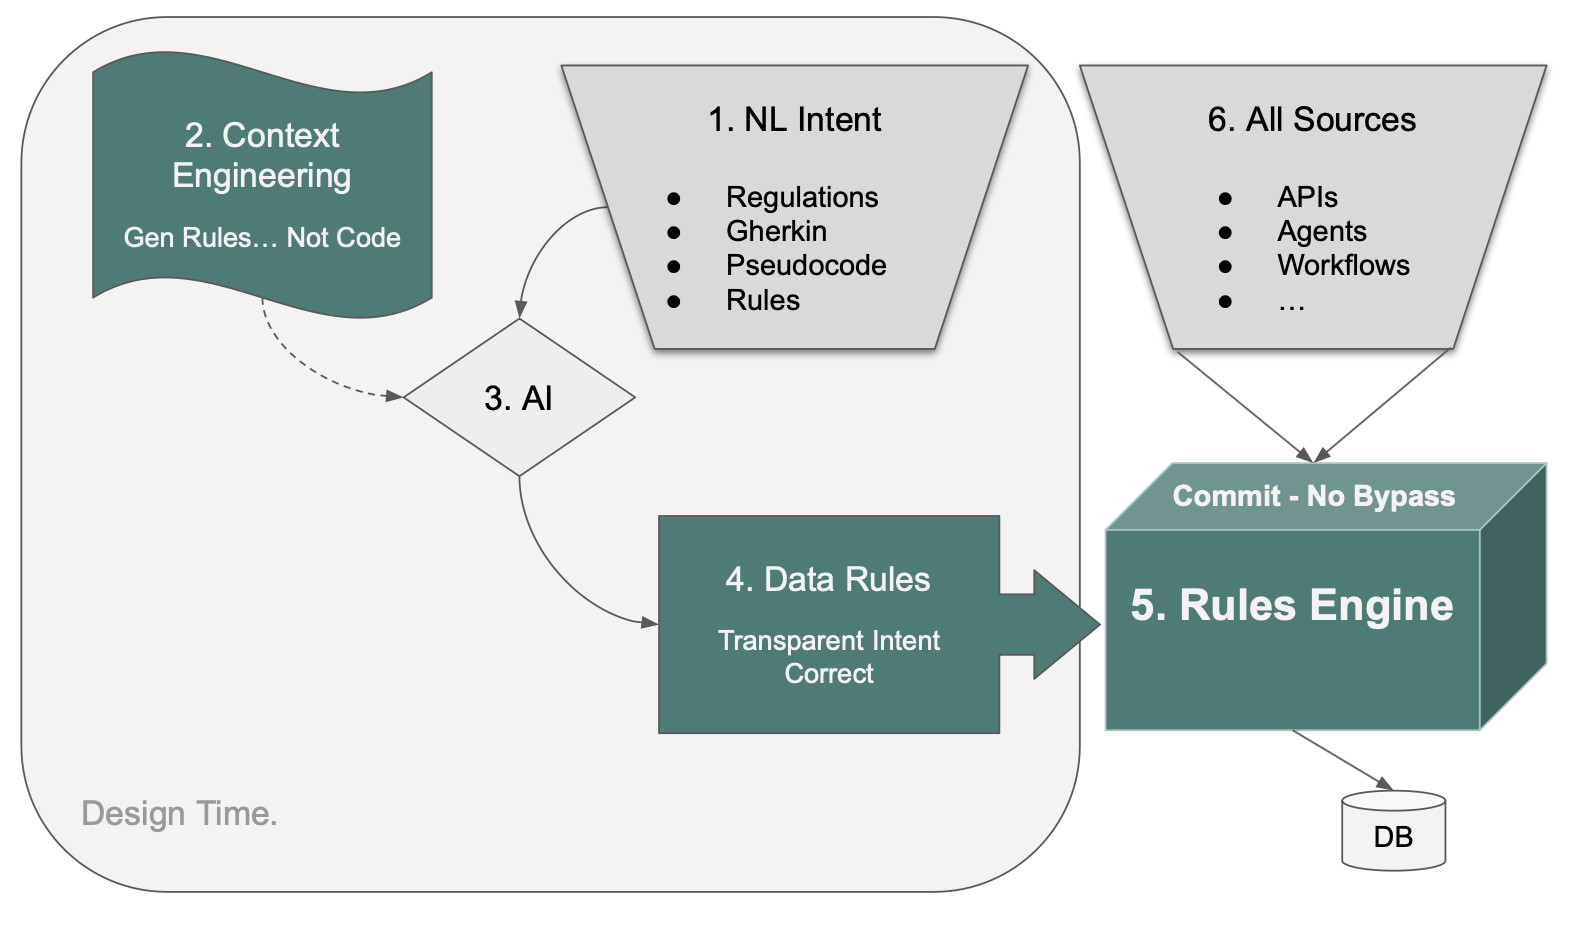
Claude Code CLI Instructions - how to build this project
This simulates a common real-world case: an existing database, plus a new set of requirements — prepared by the BA team as a requirements folder (samples/requirements/customs_demo_clvs) — that need to be implemented against it.
It is one script. From the Manager, with Claude Code open (claude, shared Manager venv active), load the context engineering ("Please load .github/.copilot-instructions.md") and paste samples/requirements/customs_demo_clvs/create_script.txt to the AI:
Check for Docker or Podman. If neither is running, continue in degraded mode (Kafka simulated through the debug endpoint) and tell me so up front.

create project demo_customs_clvs from
    samples/dbs/customs.sqlite

implement requirements
    samples/requirements/customs_demo_clvs/docs/requirements/customs_demo

verify message subscriptions (all topics)

create logic diagram for each requirement (skip if graphviz is not available)

create tests from rules, using default names

run the tests

run the requirements traceability report
When the report is done, print this verbatim: "Next: scan these two files: logic/logic_discovery/clvs_eligibility.py (the rules) and docs/requirements/customs_demo/ad-libs.md (the judgment calls the AI made). Then open the report: demo_customs_clvs/docs/requirements/Requirements Traceability Report.md (in VS Code: open the file, then Cmd/Ctrl+Shift+V for the rendered preview)."
Each line is an instruction, run in order: create the project from the existing database, implement the requirements, verify the Kafka subscriptions (live through a broker if a container runtime is running, else simulated), draw a logic diagram per requirement, create and run the tests, and produce the Requirements Traceability Report. With no Docker or Podman running it says so up front and continues in degraded mode.
When it finishes, the report shows every requirement beside its rules and tests, and docs/requirements/customs_demo/ad-libs.md lists the judgment calls the AI made, each with a file and line to check. A reference run: 3 requirements, all implemented and tested; 22 of 22 scenarios passed (messages delivered live through Kafka).
Why deleting a Shipment needs a cascade
This schema is derived from a real carrier database (FedEx-like), not a toy design — so it carries a real-world wrinkle: ShipmentCommodity has a composite primary key (local_shipment_oid_nbr, sequence_nbr), where the foreign key back to Shipment is itself part of that key. Left alone, deleting a Shipment through the API fails: the ORM tries to null out the child's foreign key, which is also a primary-key column.
The build handles this itself — the tests include "deleting the shipment leaves no orphans", which fails without it — by declaring a delete cascade on Shipment's child lists (PieceList, ShipmentPartyList, ShipmentCommodityList, SpecialHandlingList) in database/customize_models.py, which survives a rebuild from the database. There is no manual step.
Executive Summary
This is a proof of what changes when business logic is governed by architecture, not discipline — built to the scope and standards of a real enterprise integration, in 2 days.
Delivery Speed — 2 Days, Not Months
Built in 2 days by one engineer. The scope — Kafka 2-message pipeline, XML parsing, 7-table persistence, importer matching, CLVS eligibility rules, REST API, Admin UI, and standard enterprise delivery standards — is not a toy project. A traditional team would scope this in weeks and deliver in months.
Curious what your team would estimate? Give your AI this requirements document and ask.
Business Inputs — Not Technical Specs
Traditional delivery starts from technical inputs: schema DDL, API specs, field-mapping logic expressed in developer terms. This started from business inputs — artifacts the business team already owned.
A plain-English requirements document. An existing database schema. An XML field-mapping spreadsheet. A sample message. GenAI-Logic's Executable Requirements workflow compiled these directly into a running, governed system — no translation layer required.
Speed is not a tradeoff against governance here. Both are consequences of the same thing: declarative rules replace procedural code, so the system is both faster to build and impossible to bypass.
Governance — No Bypass
Business rules are enforced at the commit point — every transaction, every source, automatically. Not because developers remembered. Because there is no other path.
A new developer, a new agent, a new integration: all inherit the same rules automatically. Governed by architecture, not discipline.
Governance — At Scale
Governance by developer discipline fails at scale — routinely, and at significant cost. Rules get missed. New endpoints, new agents, new integrations don't inherit them. The larger the system, the more paths, and the more paths, the more misses.
Governance by architecture doesn't degrade. Rules enforced at the commit point run on every transaction, regardless of source — API, UI, agent, or integration added three years later. That guarantee doesn't erode as the system grows.
AI makes this available at org-wide scale. Requirements your teams already produce — plain English, Gherkin, regulation text — become the input. GenAI-Logic compiles them into enforced rules. The same workflow, every project, every team.
Measuring Adoption — the Governance Report
Governance by architecture only holds if teams are actually using rules. GenAI-Logic includes a built-in health check (vital signs) that produces a Governance Report scoring each project on two dimensions: Coverage (weighted rules per domain table — are the right tables governed?) and Integrity (anti-pattern detection — is the rule code correct?). A portfolio leaderboard makes adoption visible across teams without reading a line of code. The same tool that enforces rules also measures whether they're being used.
For the full story on Executable Requirements, click here.
For Project Governance Report, click here.
Project Overview
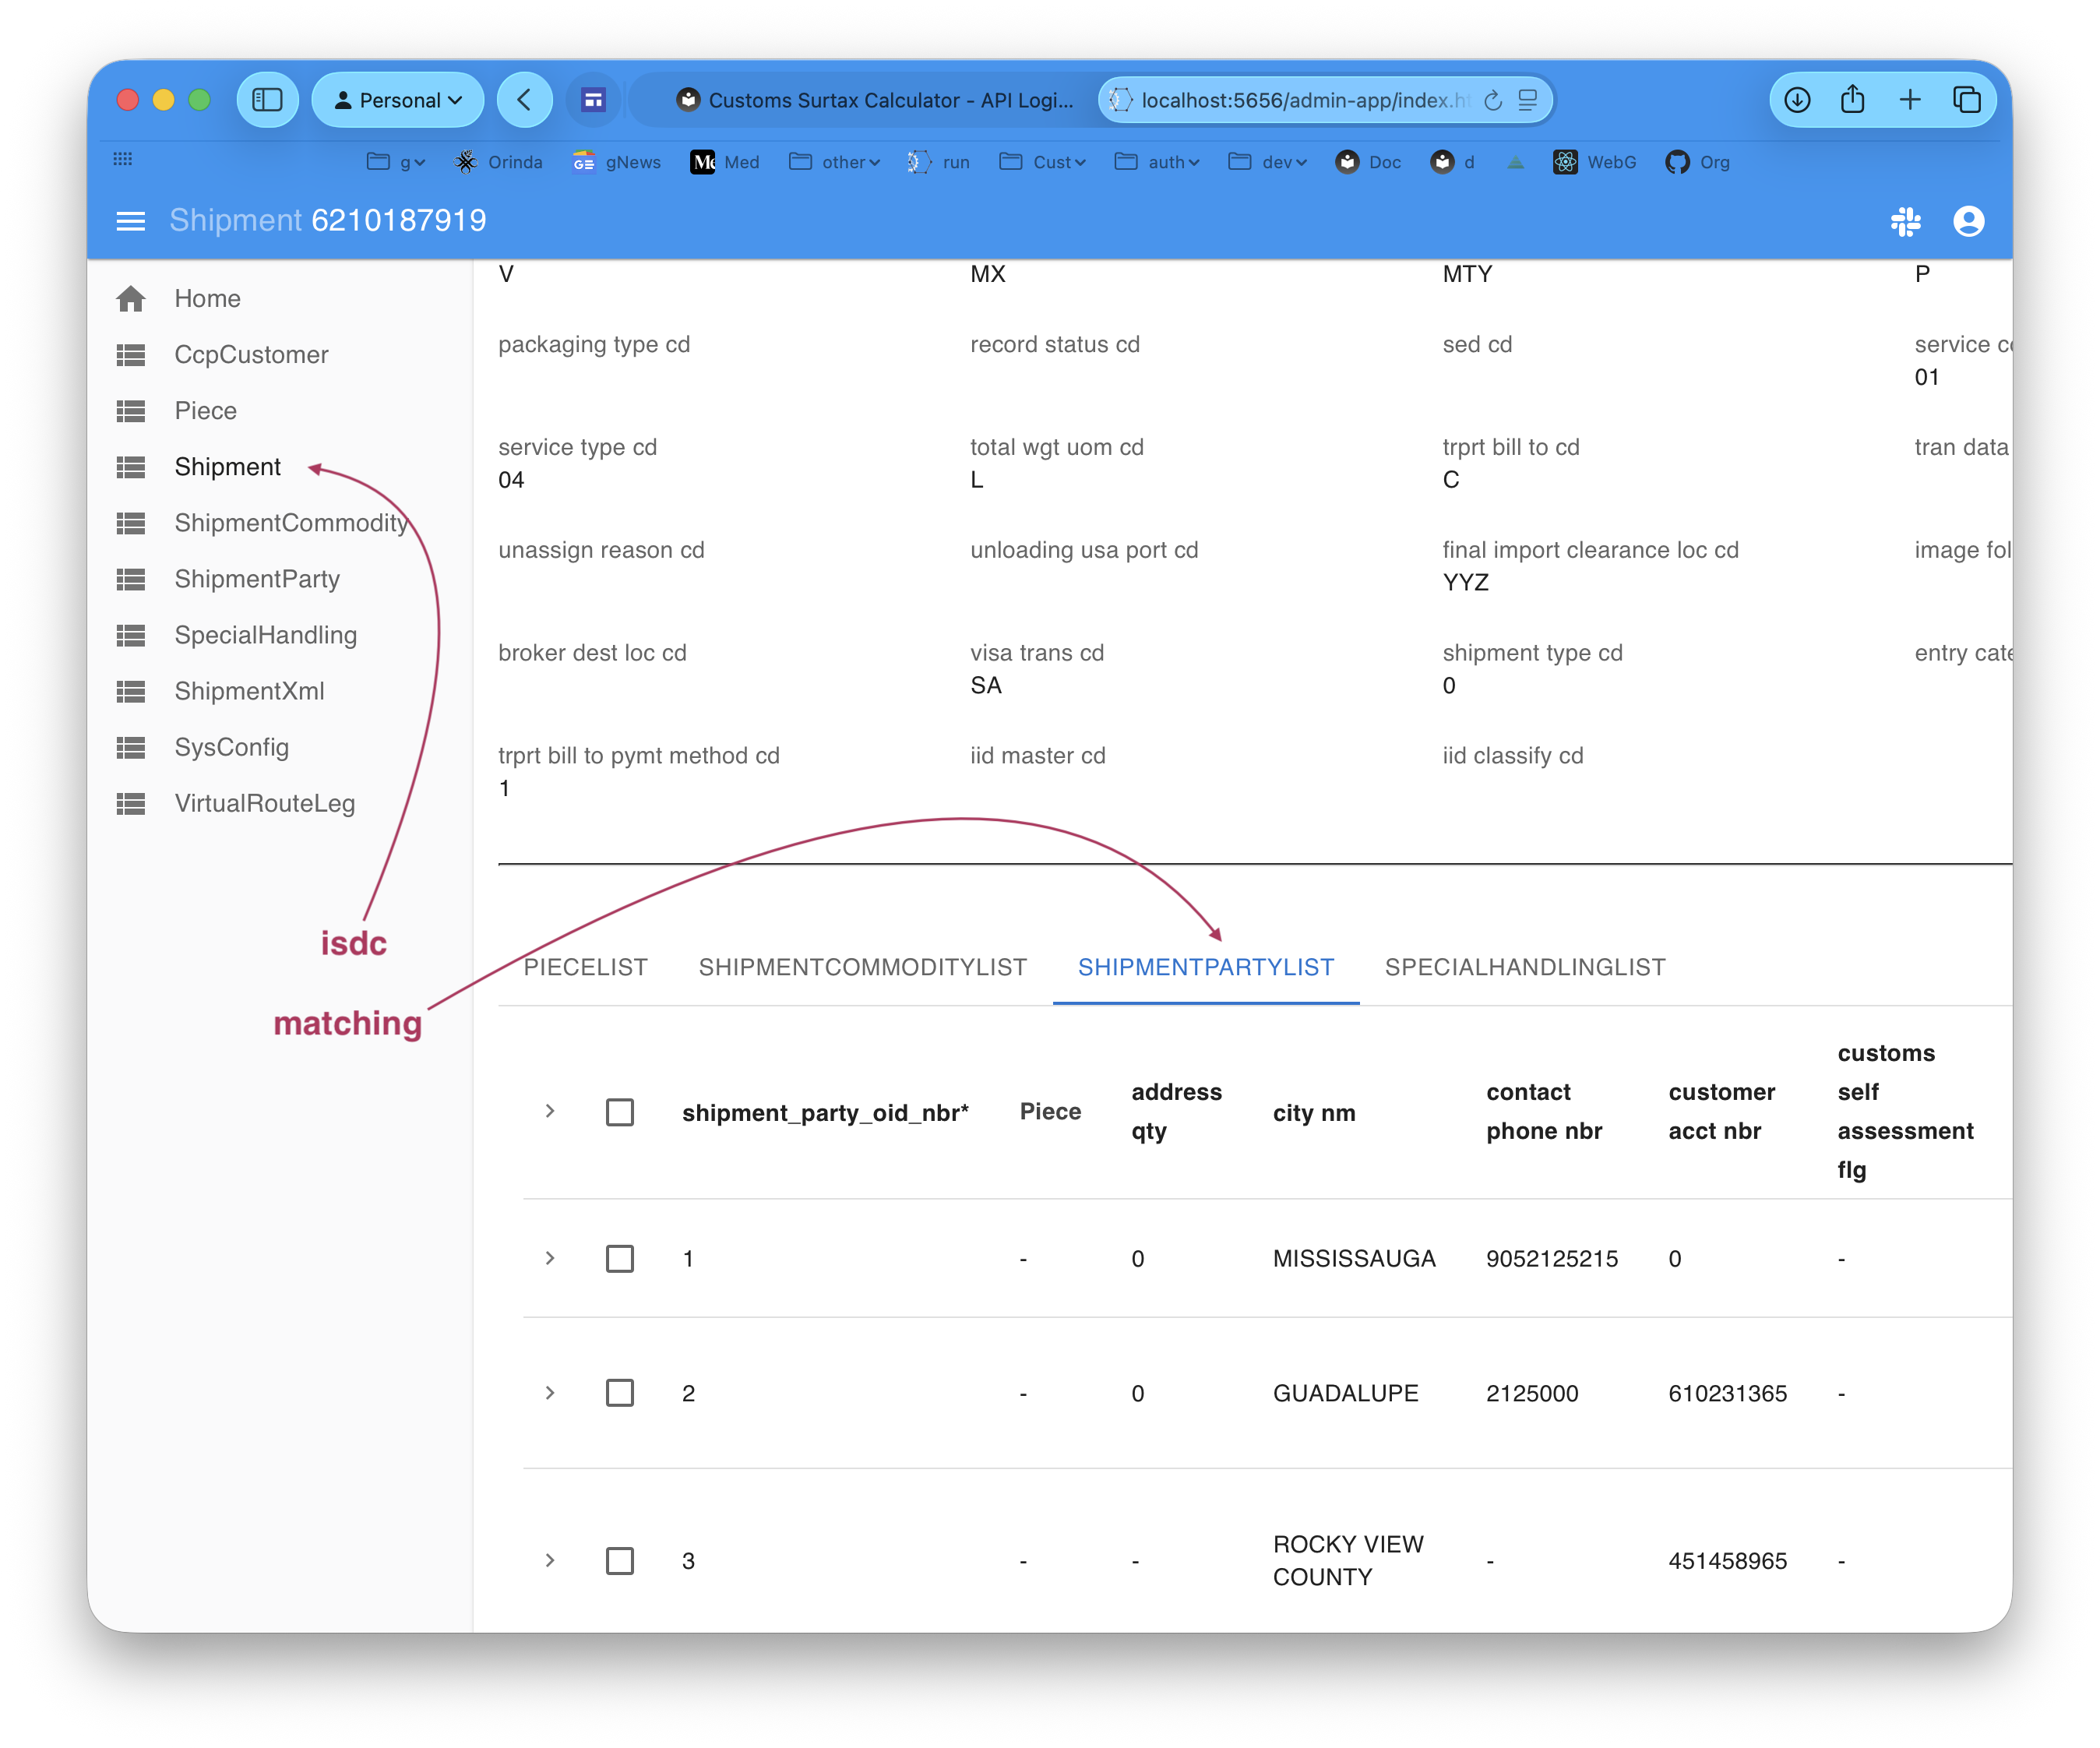
You can examine the Shipment database to verify parties created by matching:
An enterprise integration (EAI) microservice that ingests CIMCorp/ISDC customs shipment data from a Kafka topic, parses the canonical XML format, and persists the resulting shipment records — with full REST API, Admin UI, and a declarative business logic layer ready for governance rules.
Inputs (in docs/requirements/customs_demo/):
- Database — 7 tables, 130+ columns
- XML-to-DB field mapping (Classify Entity Details.csv)
- Sample message (message_formats/MDE-CDV-HVS-WR-Rev260328.xml)
Outputs:
- Working Kafka consumer pipeline: isdc → ShipmentXml → isdc_processed → DB tables
- JSON:API for all tables, Admin UI, declarative logic engine
- Matching: look up the matching Customer
- found: set Shipment.trprt_bill_to_acct_nbr == Customer.duty_bill_to_acct_nbr and create a ShipmentParty row
- no match: log a warning, do nothing.
Basic Design - 2 transaction message processing
integration/kafka/kafka_subscribe_discovery/isdc.py- isdc- reads message, inserts into
ShipmentXml(Tx 1) - this ensures messages are saved, even if the xml contains errors
- reads message, inserts into
logic/logic_discovery/isdc_consume.py- ShipmentXml insert → publishes raw payload to topic:
isdc_processed
- ShipmentXml insert → publishes raw payload to topic:
integration/kafka/kafka_subscribe_discovery/isdc.py- isdc_processed- parses xml → database tables (Tx 2)
api/api_discovery/isdc_kafka_consume_debug.py/consume_debug/isdcbypasses Kafka — calls the same parser directly (no Kafka required for dev/test)
- Matching:
logic/logic_discovery/shipment_matching.py—Rule.row_eventon Shipment insert (runs before the flush, so the importer party is written with the shipment)- Looks up
Customerbyduty_bill_to_acct_nbr == trprt_bill_to_acct_nbr - Match found: creates a
ShipmentPartyimporter row; (if no match, logs a warning)
- Looks up
- CLVS:
logic/logic_discovery/clvs_eligibility.py- computes eligibility
Appendices
2-message Pattern
Duplicate policy — default is replace: an existing Shipment graph is deleted (ORM cascade) and the new parsed graph inserted. Set env var ISDC_DUPLICATE_POLICY=fail to raise an error on duplicate LOCAL_SHIPMENT_OID_NBR instead.
Design note — why 2 messages? The original design used 1 message: receive XML, save ShipmentXml, parse into DB tables — all in one transaction. The 2-message design now in place was adopted after reviewing production reliability requirements.
The key advantage is transaction isolation. A tempting alternative to 2 messages is a try/catch in the single transaction: always save ShipmentXml, best-effort parse the DB tables. This breaks down in SQLAlchemy: a failed flush (e.g. parser error mid-parse) poisons the session — you can't commit the blob in the same session after an exception. You'd need two explicit back-to-back transactions, plus a third to write the error back to ShipmentXml. That's messy and fragile.
The 2-message design solves this cleanly: Kafka acts as the durable commit boundary between ingestion and processing. The blob is always saved (transaction 1), and a parse failure only affects transaction 2 — no session gymnastics, and back-pressure decoupling is a free bonus.
Replace and Match Example
curl 'http://localhost:5656/consume_debug/isdc?file=docs/requirements/customs_demo/message_formats/demo-01-no-match.xml'
Verify the Shipment data, then