Standard Requirements
 TL;DR: From Standard Specs, native AI Generates Code With Missing Services... Rules Don't
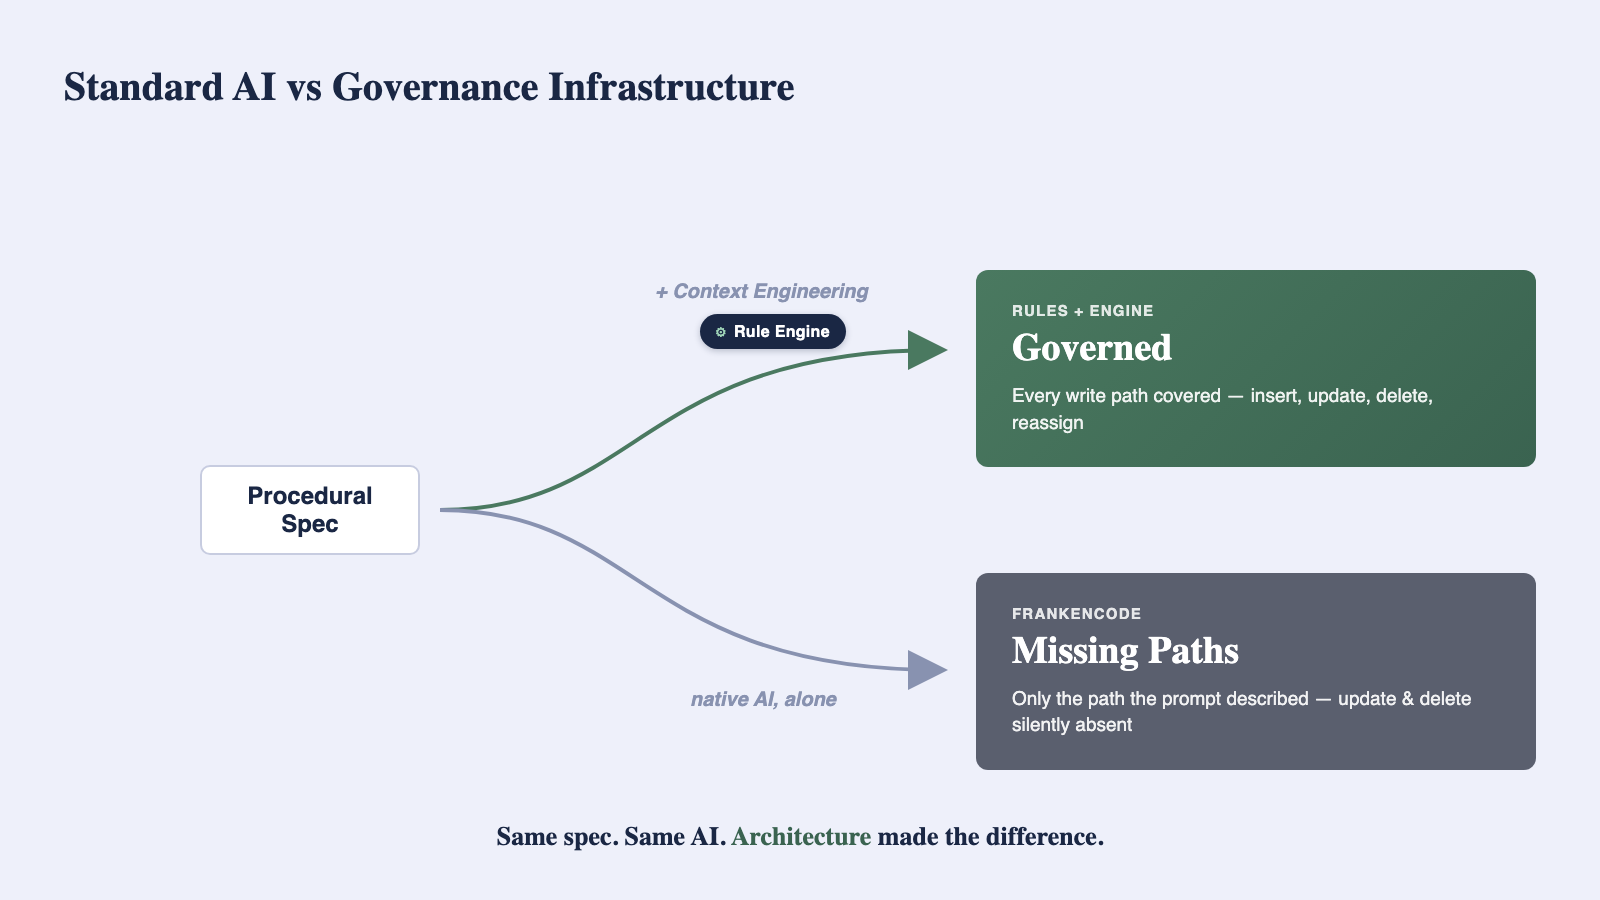
In this study, we submitted standard procedural specifications to AI, and found that it generated systems missing core services such as delete and update.
Rules understand dependencies, and how they affect all verbs. So, the solution:
Pair a rules engine with Context Engineering so that AI generates rules, not code.
This provides the governance enterprises require.
How Does Native AI Handle a Typical Spec?
AI Taught the Wrong Lesson.
Funny story. A while back I asked my AI assistant for an example of a business rule, just to show someone how it's done. It gave me this:
On Placing Orders,
Derive item amount as quantity times Product Price
Add that to the Order Total Amount
Add that to the Customer Balance
Ensure that is less than the Credit Limit
I gasped. Here was AI teaching people the wrong paradigm — procedural, focused on one event.
What if it actually created code like that instead of rules?
Then It Passed the Test Anyway.
Well, models were improving, so I gave it a try. I created a project, submitted that same procedural text, to see what it would create. I got:
Rule.copy(derive=Item.unit_price, from_parent=Product.unit_price)
Rule.formula(derive=Item.amount, as_expression=lambda row: row.quantity * row.unit_price)
Rule.sum(derive=Order.amount_total, as_sum_of=Item.amount)
Rule.sum(derive=Customer.balance, as_sum_of=Order.amount_total, where=lambda row: row.date_shipped is None)
Rule.constraint(validate=Customer, as_condition=lambda row: row.balance <= row.credit_limit, ...)
Declarative Rules. Whew! OK, joke's on me.
But specs are often procedural
But it raised a real question.
Specs are often procedural - it's a natural way to think. How would "native" AI translate such specs?
I'd made the case for governed rules at enterprise scale before, in AI With Rules You Can Read, Trust, and Maintain. But that's an argument. This is a test.
There's a real principle at work here: good architecture should work with what you naturally do, not require you to conform to its model — like how a spreadsheet matches how financial analysts think.
So, let's run an A/B test: the same natural (procedural) spec, once through native AI, once through AI governed by rules.
Using basic_demo.sqlite, build a system (api + web app) that lets us enter orders.

Here's what needs to happen when someone places an order:

- For each line item on the order, look up the product's price and multiply by the quantity to get the item's amount.
- Add up the item amounts to get the order's total.
- Add the order total to the customer's balance.
- Before we let the order go through, check that the customer's balance doesn't go over their credit limit — if it would, reject the order.
A) Native AI
Handed straight to native AI, verbatim, to two frontier models — with an added instruction not to reach for our own stack:
Only the Insert Path Was Built
Both native models wrote the same shape of system:
def place_order(db, customer_id, notes, line_items):
    ...
    new_balance = (customer.balance or Decimal("0")) + order_total
    if new_balance > customer.credit_limit:
        raise OrderRejected(...)
    order.amount_total = order_total
    customer.balance = new_balance
    db.commit()
One function, wired to order creation. Fundamental logic missing: no update path, no delete path.
I probed it:
- Changed an item's quantity
- Deleted an item
- Reassigned an order to a different customer
- Reassigned an item to a different product
Every case, both models, left stale data behind. No error. Nothing to catch it. The logic wasn't buggy so much as absent — it existed for exactly one path and nowhere else.
B) Governed AI
I ran the identical prompt through GenAI-Logic. As noted above, five rules came out:
Rule.copy(derive=Item.unit_price, from_parent=Product.unit_price)
Rule.formula(derive=Item.amount, as_expression=lambda row: row.quantity * row.unit_price)
Rule.sum(derive=Order.amount_total, as_sum_of=Item.amount)
Rule.sum(derive=Customer.balance, as_sum_of=Order.amount_total)
Rule.constraint(validate=Customer, as_condition=lambda row: row.balance <= row.credit_limit, ...)
All Paths Covered
None of them says "placing an order." Checked live against a running server, all four cases came back correct:
- Change the quantity → the total updates
- Delete the item → the balance drops back
- Move the order to a new customer → old balance down, new balance up
- Move the item to a new product → the price re-copies
That's not a style preference — it's the whole point. "On Placing Orders" only covers placing an order. These 5 rules cover every path to the same data: change a quantity after the fact, delete an item, ship the order, move an item to a different order, move an order to a different customer. Same 5 rules, every time — because they're declared on Item.amount, Order.amount_total, and Customer.balance themselves, not on the moment someone places an order.
Think of a spreadsheet. B10 = SUM(B1:B9) doesn't get called when a value changes — it just reacts, automatically. Nobody writes a handler for "what if row 4 changes" versus "what if row 7 is deleted." The formula is declared once, on the data, and it's correct no matter which cell moves. That's what these 5 rules are doing with Order.amount_total and Customer.balance — the same automatic reaction, just across tables instead of cells.
Governance by Architecture, Not Discipline
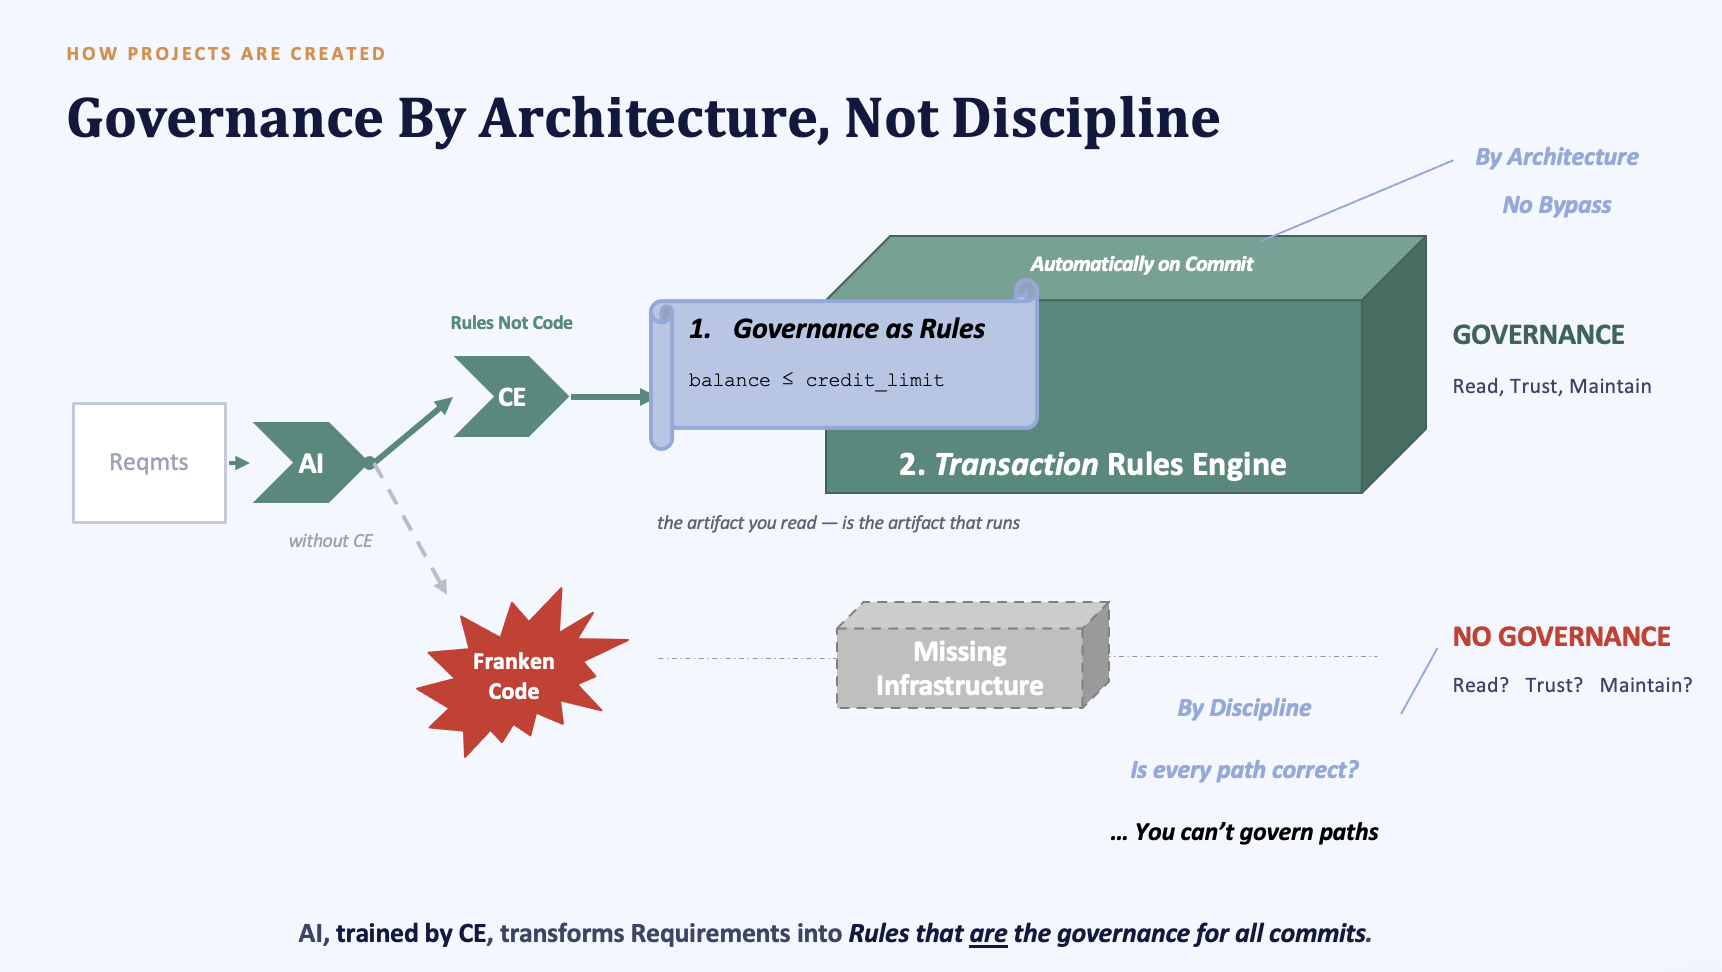
Governed by Architecture has 2 key elements:
- A rule engine that understands the dependencies — it knows
Customer.balancedepends onOrder.amount_totaldepends onItem.amount, so it adjusts it, automatically, on every write, whether or not the code in front of it ever mentions "placing an order." It runs as a listener on the commit itself, not inside any particular API or handler — so it governs every path, from every transaction source, the same way. That adjustment, not a full recompute, is what keeps it fast at scale — this isn't a RETE engine re-evaluating everything from scratch. - Context Engineering that instructs the same AI to write rules, not code — the same model that wrote the frankencode above, writes 5 rules.
Governed by discipline is the alternative — every developer, on every team, on every project, has to remember every pattern, every time. AI doesn't change that math; it just adds another party who has to remember. With architecture, nobody has to. It lives in the engine, applied the same way every time — with or without a smarter model underneath it.
In most large companies, governance means a review cycle: someone signs off before a change ships, someone audits after the fact. That works, but it's a human checking a human.
Rules that run this way at commit — no bypass — make governance something the system does, not something a committee does later. Every transaction source, every path, every time.
AI Makes Mistakes — Which Is Why Readability Is Critical
Here's a mistake worth owning: the very first rule set in this article included where=lambda row: row.date_shipped is None on the Customer.balance rule — a shipped-orders filter this prompt never asked for. Compare it to the second rule set, later in this piece, for the same requirement — that clause is gone. I caught it and dropped it, but not before it sat there, unremarked, in what I'd already called "declarative."
Nobody said anything about shipping. AI added it anyway, echoing a different example it had seen before.
That's a real error. AI makes them.
But look at where it was sitting: one clause, on one line, in a 5-line rule set, in plain English terms — "sum of Order amount_total where date_shipped is null." I read it, recognized it didn't belong, and removed it. Took a few seconds.
That's a separate argument from reuse. Rules cover every path automatically — but readability is what lets you catch AI when it gets one wrong.
That's how 5 lines of logic become 5 rules — not ~200 lines of frankencode you can't read, spread across handlers and queries, with the same mistake buried three calls deep where nobody will ever find it.
You can't govern what you can't read.
Following Up on the Bugs
An obvious objection to the native-AI result: nobody ships the first draft. A developer would test it, notice the update and delete paths were missing, and ask AI to fix them. Quite so.
So that's what I tried next — three rounds, each a realistic bug report a developer would actually write after testing the app:
- "It only handled inserting a new order — it failed when I update a line item. Please fix." Result: quantity and product changes on an existing item both started working correctly.
- "Editing items works now. But adding a new item to an existing order doesn't update the total, and deleting an item doesn't either." Result: both fixed, cleanly, with no regressions.
Each round, native AI fixed exactly what was reported, correctly. Three rounds in, order creation and full item-level editing all worked. That's a real result, and it matters: iteration works, AI responds well to a clear bug report, and the fixes were not superficial patches — the same code paths were correctly reused across the three rounds.
It also means the burden of finding every gap now sits with the team. Each of these three fixes exists because someone tested that specific case and wrote it up. Nothing in the fix generalized to a case nobody had tried yet.
If Your Team Keeps Working the Way It Does Today
If your developers keep writing specs and reviewing code the way they do now, and you simply add AI to the process — what changes?
Less than it looks like. AI finds and fixes each gap fast, once someone's tested for it. Who's responsible for knowing whether every path is covered doesn't change at all. Still your team, still by hand, one test at a time.
Better prompting or stricter test scaffolding might close some of this without touching the architecture at all — we didn't test that variant here. What we did test is the bare process, three rounds of it, and the bare process didn't generalize on its own.
The comparison doc's bugs — forget the old balance, forget to re-copy the price — were corner cases inside code that mostly worked. This test found something plainer: no update logic, no delete logic, for a spec written the ordinary way. Three rounds of real fixes later, that original bug was still there. Nobody had hit it yet.
And the original comparison shows what reviewing that gap by hand actually costs — even from a clean, declarative spec: roughly 200 lines of procedural code, for what became 5 rules here.
This isn't just one project's finding. 52% of organizations already use AI across multiple business functions. Only 17% say governance is "embedded by design" — OneTrust's 2026 AI-Ready Governance Survey, 1,200+ business leaders. The gap between adoption and governance is industry-wide, not a one-off.
The Root Cause, and the Way Out
AI-assisted development still has a quality problem for business logic. That's not news.
This test identified a root cause: the AI kept thinking procedurally. The spec was procedural. The follow-up prompts were procedural. Every fix was one more procedural patch.
Adding AI on top of that doesn't change it. AI just writes the next patch faster. Three rounds running.
Two ways to close the gap:
- Change how the team thinks. Invariants on data, not steps in a process. Real skill, slow to build — the same adoption problem that made declarative rules a hard sell for decades before AI existed.
- Change what the AI is aimed at. Same spec, same process, translated into rules instead of code. Every path tested here came back correct — no change to how the team works.
The fix isn't asking anyone to think differently. It's giving their existing way of working an architecture that doesn't depend on catching every path by hand: a rule engine, plus Context Engineering that directs AI to write rules, not code.
See the Full Projects
Both sides of this test, unedited — inspect the code on GitHub, or run them yourself: start at www.genai-logic.com, then open in Codespaces.
- Native AI, no rules engine: inspect on GitHub — the prompt, the code, the transcript
- GenAI-Logic: inspect on GitHub — the same prompt, the 5 rules, all paths verified